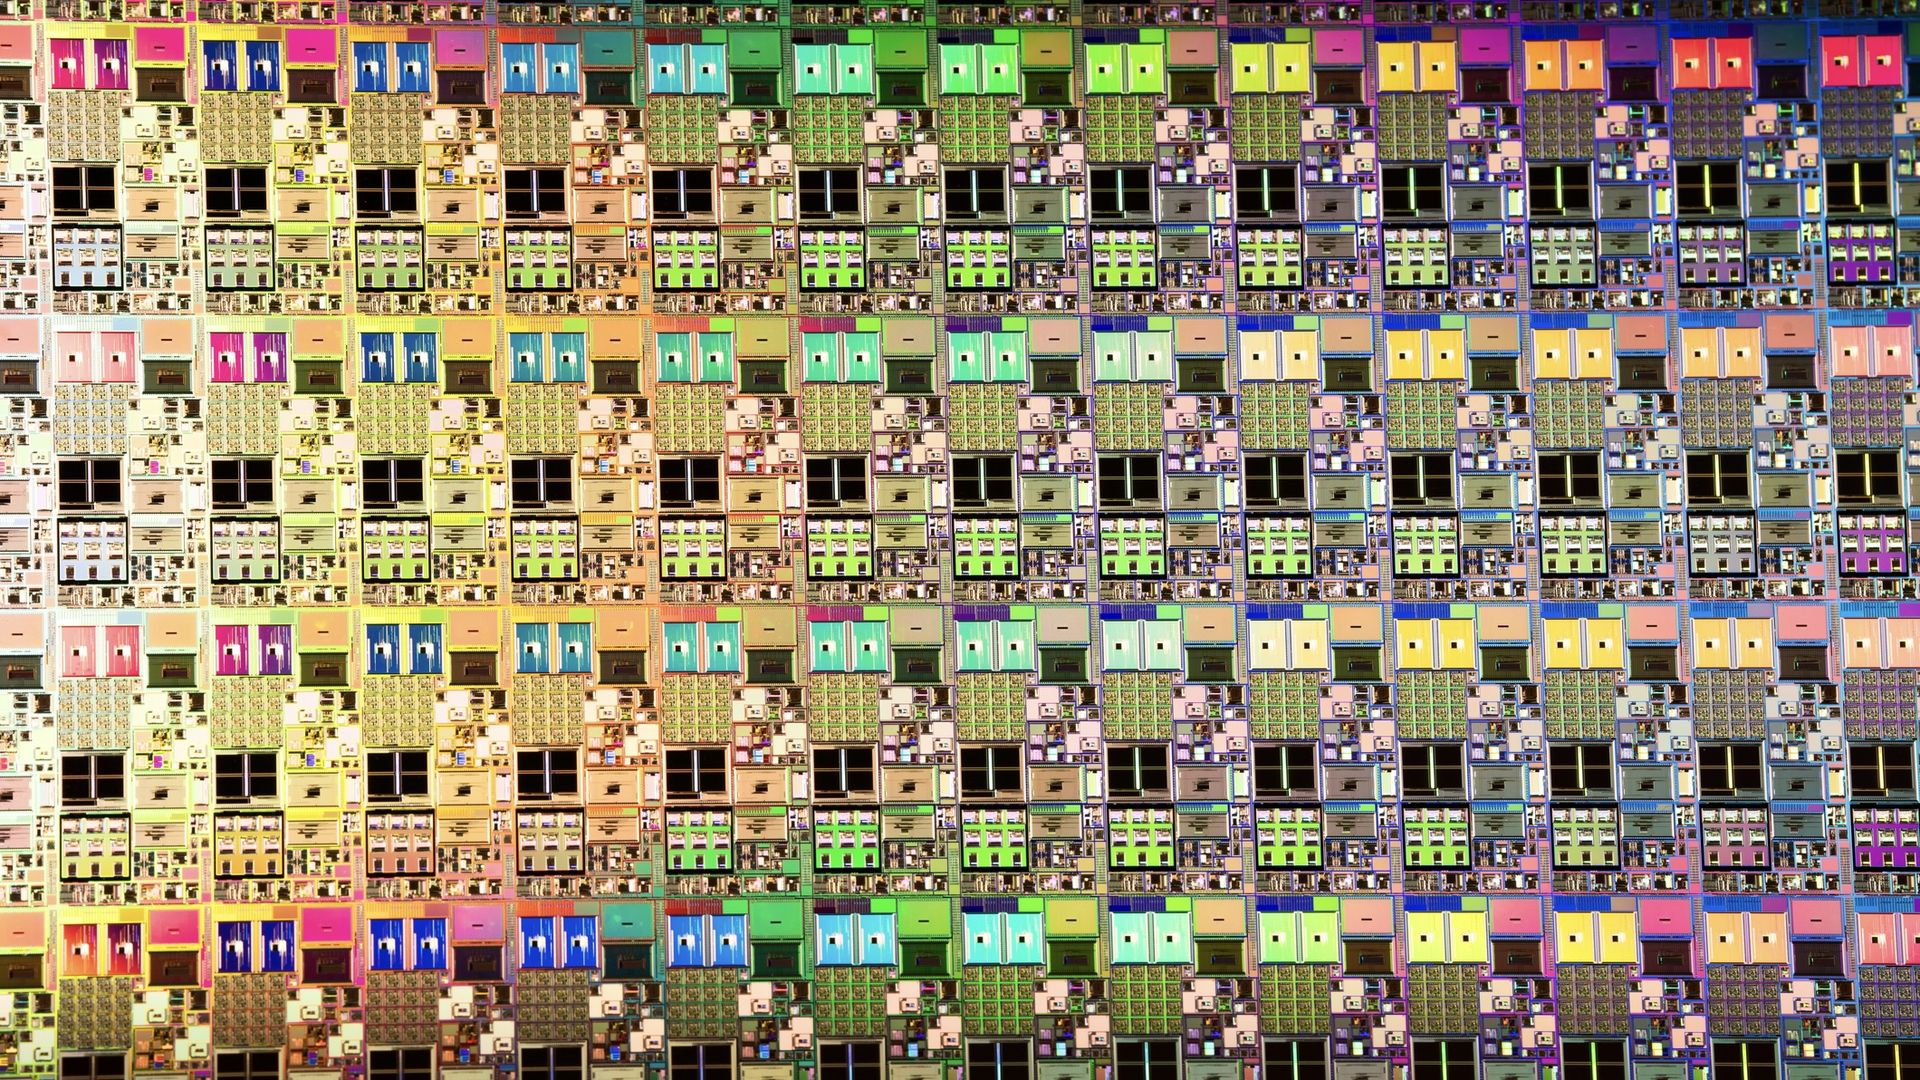
Engineers in China have built a new computer architecture they say can one day make up to a million artificial intelligence (AI) chips work as one. For comparison, Elon Musk's AI company, SpaceXAI (soon to be SpaceXSI), describes its Colossus cluster as the world's most powerful AI training system, comprising 200,000 interconnected chips.
Traditionally, the AI chips used to train foundation models are housed in separate servers and communicate over a network to share data and divide workloads. But the new architecture, Peerium, uses a high-speed interconnect system designed to maintain efficient communication between chips across multiple racks, even as the number of chips scales into the hundreds of thousands.
Huawei unveiled the new architecture Sept. 17 at the company's annual CONNECT conference.
Representatives from Huawei said in a statement that computers powered by Peerium could train models with up to 40 trillion parameters. For comparison, competing hardware, like GB200 NVL72 from NVIDIA and CS-3 from Cerebras, have reported training at the trillion-parameter scale, rather than the tens-of-trillions.
"Over the next two years, there will be roughly 6 or 7 frontier AI labs in China, and all will aim at training foundation language models of sizes ranging from 10 to 40 trillion parameters," Liao Heng, chief scientist for Huawei's chip design arm HiSilicon, told the Associated Press. "So you need such a scale of infrastructure to train these models."
Peerium's performance relies on three elements: nested parallelism, unified memory addressing, and peer-to-peer interconnects, Huawei representatives said in the statement.
Nested parallelism allows workloads to be broken into smaller tasks and organized across hierarchical groups of chips that work in parallel. It's similar to how a company breaks down work into departments and then smaller teams, all of which coordinate their efforts toward a common goal. Unified memory addressing allows processors to access memory across other servers, as opposed to only that attached to the processor's own server. Peer-to-peer interconnects allow components to communicate more directly with one another, rather than relying on an intermediary.
All three principles are designed to make more efficient use of computing resources so that a single system can coordinate larger numbers of chips to handle demanding AI workloads.
According to Huawei, existing interconnect technologies — which link processors and servers to enable them to communicate — cannot support the Peerium architecture at the scale it envisages. For instance, NVIDIA uses NVLink for communication within racks and InfiniBand for communication between racks. The inter-rack communication bandwidth in this setup is 200GB per second, Eric Xu, Huawei's rotating chairman, told the AP.
"With such a low inter-rack communications bandwidth, there is no way you can make one million processors work as one computer," he said.
Huawei instead developed its own interconnect technology, UnifiedBus, which the company says delivers inter-rack communications bandwidth of up to 800GB per second.
"When one million processors work as one computer, this lays the foundation for better and more efficient AI training and inference," Xu added. "Therefore, I see UnifiedBus as the path for the future AI era. I believe, in the years to come, other players would certainly follow suit."
Stitching together a computing network
Alongside Peerium, Huawei also announced the Atlas 950 SuperPoD, a computing system built on Peerium and powered by more than 8,000 Huawei Ascend 950DT AI accelerator chips.
Related storiesScientists build specialist 'AGI processor' that they believe will power the next wave of AI agentsScientists say they've eliminated a major AI bottleneck — now they can process calculations 'at the speed of light''Beyond human intuition': AI designs chip components 500 times smaller than what engineers could ever imagine
Xu said testing for AI training is underway on these SuperPoDs and that results show that they use their available computing power for AI training more efficiently than AI computing clusters that aren’t based on Peerium and UnifiedBus.
Huawei expects to begin supplying the SuperPoDs by early next year, at the latest, before its SuperClusters, which link multiple SuperPoDs to form a larger AI computing system, based on Peerium, eventually come online. Representatives said that one SuperCluster with 256,000 computing cards — hardware modules that add processing capacity — is currently being deployed and tested.
Models with large numbers of parameters demand greater computing resources and infrastructure, which isn't always desirable as it increases costs. In the summer, researchers used an IBM quantum computer to reduce the perplexity of Meta's Llama 3.1 8B language model — a measure of how well it predicts the next word or token — while keeping the number of parameters almost unchanged.
Hence then, the article about huawei unveils supercluster architecture designed to make 1 million ai chips work as a single computer was published today ( ) and is available on Live Science ( Middle East ) The editorial team at PressBee has edited and verified it, and it may have been modified, fully republished, or quoted. You can read and follow the updates of this news or article from its original source.
Read More Details
Finally We wish PressBee provided you with enough information of ( Huawei unveils 'SuperCluster' architecture designed to make 1 million AI chips work as a single computer )
Also on site :
- ‘Boy Meets World’ Star Rider Strong Reveals He Got ‘Completely Screwed’ During The Show’s Final Season
- Walmart’s Fluted Cabinet Brings Mid-Century Modern Charm and Tons of Storage to Small Bathrooms, Now 50% Off
- Is ‘I Play Rocky’ Original or Adapted? Stallone’s ‘Rocky’ Origin Story Faces a ‘Barbie’-Style Oscar Dilemma (EXCLUSIVE)